
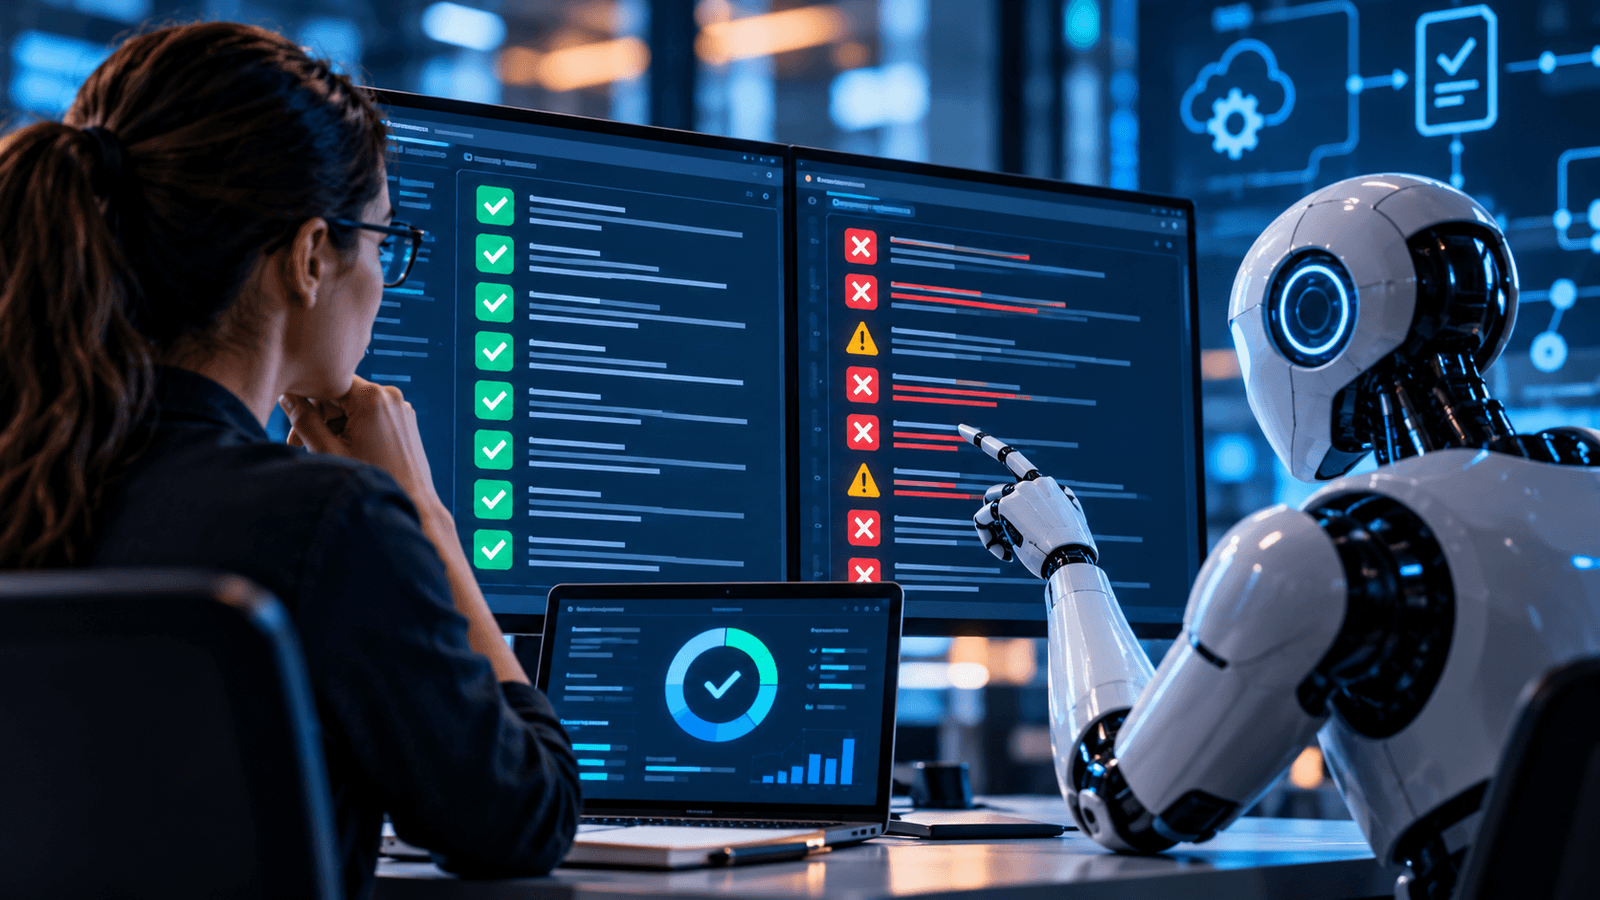
Every demo from an AI testing tool vendor ends with a promise to cut test design effort from hours to minutes. Surprisingly, one important question is missing from these conversations: How many of those test cases can QA teams truly trust when testing a business-critical workflow such as payments?
The AI Testing Efficiency Trap
Many QA leaders use just test case counts and effort savings to show the success of AI implementation. The coverage gaps in AI-generated cases can be costly and won’t surface for months until they show up as a customer-reported bug. A small controlled study by Thoughtworks on AI-generated test cases found that roughly a quarter of AI-generated cases were not clear enough to trust without rework.
A fintech client that I worked with last year was thrilled by an internal demo where the team generated 250+ test cases in just 1.5 hours. However, this excitement only lasted for a few days. The team had to spend a full sprint reviewing those tests to fix the coverage gaps. The review exposed a different reality. 30 of them were testing the wrong field entirely and 60 of them were found to be redundant. This experience is a reminder that speed and efficiency are not the only things that matter when using AI for testing.
The Hidden Cost of AI-Generated Test Cases
The problem with AI-generated test cases is not that they are always completely wrong. In many cases, the real problem is buried deeper. Artificial intelligence can generate test cases for wrong business rules, generate too many test scenarios for a simple requirement, generate redundant tests that don’t add any real coverage, or miss critical edge cases completely.
Testers may need to identify duplicate tests, correct wrong assumptions, combine overlapping scenarios and fix coverage gaps. The promised gains in efficiency can be easily lost if the testers need to spend additional effort to make the AI output a usable test suite.
The real worry is what happens when these problems aren’t found early on. Teams will end up spending effort to fix test quality issues during test cycles, resulting in schedule overruns. Some of those gaps may eventually surface as production defects, often after the opportunity to detect them earlier has passed.
That is why counting the number of test cases generated or measuring the time taken to generate them tells only half the story. The real question is how much usable testing value AI is creating after the review and rework are complete.
Using an AI Trust Score for Measurement
Instead of measuring AI success solely by the number of test cases generated, QA teams need a better way to assess whether AI-generated output can actually be trusted. One approach is to define an AI Trust Score by considering four factors: Acceptance Quality + Coverage Confidence + Low Rework + Defect Discovery Value.
Acceptance Quality measures the percentage of AI-generated test cases that can be added to the final test suite with minimal or no changes. Coverage Confidence covers whether the generated tests address critical business flows, edge cases and negative scenarios rather than just increasing the volume of test cases. Low Rework measures the effort required to correct the coverage gap, redundancy and other issues in the AI-generated test cases. Lastly, Defect Discovery Value helps to find an answer to a critical question: can AI-generated tests find meaningful defects that otherwise would have been missed?
QA team should introduce the trust score into their existing test case review process and monitor results over time. Teams can start with a simple scorecard to set an initial baseline and review the trends at the end of each sprint. Over time, teams can adjust the measures and assign appropriate weights, depending on the business risk.
AI earns trust when its output consistently reduces test design effort, requires minimal correction and contributes towards improving product quality.
The Shift From Speed to Trust
The fintech client in this article did not lose faith in AI-generated test generation. They lost a sprint because they had no way to quantitatively measure how many of the 250 test cases were genuinely usable. An AI Trust Score will not eliminate the need for human review, but it can help teams track the reliability of AI output over time and determine whether the technology is becoming more trustworthy or simply generating more tests to review.
The shift QA leaders need to make is to stop asking how many test cases AI can generate and start asking how many deserve a place in the baseline test suite. A successful demo may prove that AI can generate tests but only a consistent measurement can prove whether the tests are trustworthy.
Frequently Asked Questions
1. Why can't QA teams trust every AI-generated test case?
2. What is an AI Trust Score?
3. How should DevOps teams measure AI testing success?
George Ukkuru has spent more than two decades working with global enterprises on test automation, quality engineering, and DevOps transformation. He has led maturity assessments and built testing strategies for Fortune 500 organisations across multiple industries. He hosts the Automation Hangout podcast and has authored several books on test automation and quality engineering.